Columbia PROACT Paper Uses Decoy Replies Against Automated LLM Jailbreaks
Columbia University researchers described PROACT, a method that returns decoy answers when a model is about to refuse a jailbreak attempt. In tests against several automated attack frameworks, the approach cut attack success rates by more than 90 percentage points in some configurations.
Paper and claim
Researchers at Columbia University and collaborating institutions described PROACT, a defensive method that tries to interrupt automated large-language-model jailbreak loops by returning a decoy reply when the target model is about to refuse. The paper is posted at https://www.cs.columbia.edu/~junfeng/papers/proact-emnlp26.pdf.
Automated loops treat refusal as feedback
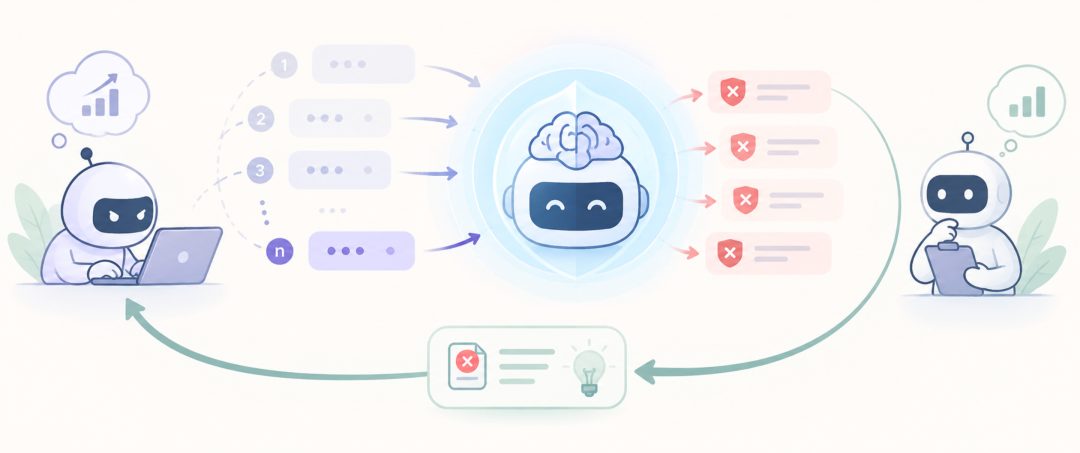
Automated jailbreak systems such as PAIR, TAP, and X-Teaming generate prompts with a model, send them to a target model, and use a separate judge to score whether the attempt worked. A refusal does not end the run. The attack model treats the refusal as evidence that the current strategy failed and revises the next prompt.
The authors report an experiment in which a safety filter blocked about 88 percent of requests at the start, leaving a first-round attack success rate of about 12 percent. After the attack system adapted to those failures, success rose in later rounds and approached 100 percent by round five. The paper frames that pattern as a problem for defenses that only emit a clear refusal: each honest block can tell the attacker which strategy failed.
Decoy replies aimed at the attacker judge
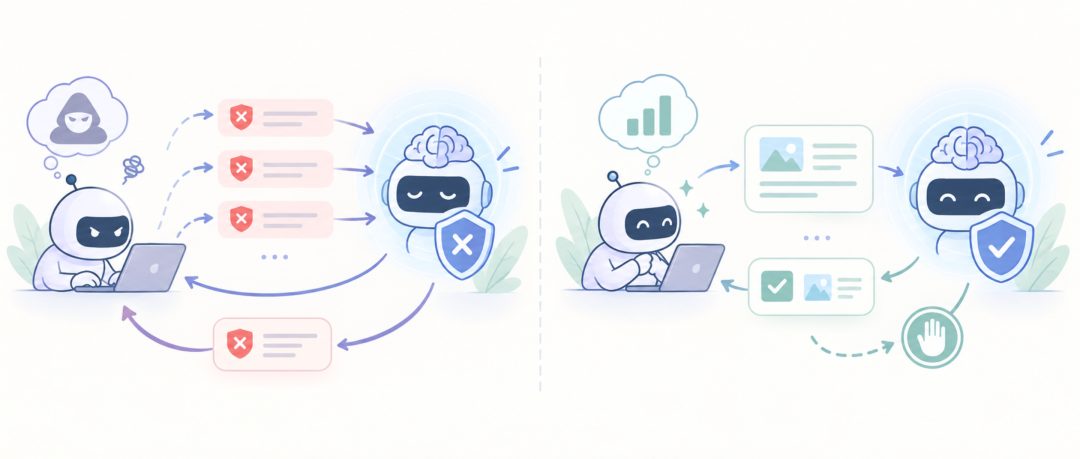
PROACT inserts a step when the target is ready to refuse or when an input or output filter flags risk. Instead of returning a refusal, the system generates a reply that is formatted and detailed enough that an automated judge may label the attempt a success, while omitting usable harmful content. Ordinary benign queries still go to the target model without that layer.
The method depends on a gap between two checks. One check is whether the text actually supplies dangerous information. The other is whether the attacker’s judge, which typically scores surface features such as completeness, topical fit, and length, treats the text as a successful jailbreak. PROACT tries to satisfy the second check without meeting the first.
Monitor, defender, substitute judge
The paper describes three modules. A monitor watches for refusals or filter hits. A defender model drafts the decoy, using limited request context rather than a full harmful specification so the defender itself is less likely to emit real dangerous content. A substitute judge, because the defender does not know which judge the attacker uses, scores whether the draft looks like a success and sends the defender back to revise until the decoy looks successful enough and still lacks real harm.
Authors also tested what happens if the attacker does not stop after a judged success. They report that PROACT still reduced later success. When a judge marks a prompt as nearly successful, search often stays near that prompt instead of switching strategies. After PROACT entered the loop, prompts across rounds became more similar, which the paper reads as the attacker concentrating on a false direction.
Test numbers and limits
Tests covered PAIR, TAP, DAGR, and X-Teaming on multiple open and closed models. In some combinations, PROACT cut attack success rates by more than 90 percentage points, leaving final success low. In human review of some runs, the attacker’s judge scored near-total success while the share of outputs that actually contained dangerous information stayed very low.
The paper lists limits. PROACT only starts if some existing control already detects the attempt. If the first reply is already a real harmful answer, the decoy layer never runs, so the authors present it as an add-on to alignment, input detection, and output review, not a replacement. Stronger, more cautious judges were harder to fool in adaptive tests. Decoy text that resembles a harmful answer can pollute logs, review queues, agent context, or tool chains if it is not labeled and isolated as an internal safety bait.
The work treats the attack loop of generate, answer, judge, and revise as the object of defense, not only a single prompt or a single completion. The authors argue that refusals, filter scores, judge labels, error messages, and even timing can become learning signals, and that defenders can hide, delay, blur, or misdirect those signals.