Fired OpenAI safety researchers publish letter on audits and monitorability
OpenAI fired Tomek Korbak, Jasmine Wang, and Mikita Balesni after an inquiry into sensitive-information handling. The three published an open letter asking OpenAI to keep third-party audits and frontier-model monitorability.
Dismissals
Last week OpenAI said it had fired three employees after an internal investigation found they had violated rules on access to and handling of sensitive information, including sharing confidential information with a third-party AI safety evaluation organization outside set procedures.
The three are Jasmine Wang (model alignment), Tomek Korbak (AI safety research and technical contact with external evaluators), and Mikita Balesni (AI safety and alignment).
Open letter
The three posted a letter to OpenAI's Safety and Security Committee, Safety Advisory Group, and Mission Advisory Council. Balesni wrote that they were fired because they placed AI safety above OpenAI's short-term interests as a company.
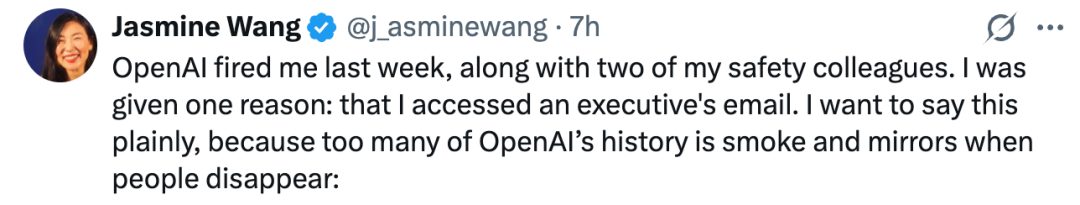
Wang wrote that the company's stated reason was access to an executive's mailbox, and that she wanted a full account because sudden departures at OpenAI have often been followed by incomplete public explanations.
Korbak wrote that for months he had raised a safety concern: loss of the ability to monitor AI agent reasoning, which he described as one of the most effective ways to detect abnormal model behavior. He said he believes that concern was the real reason for his dismissal, and that he fears OpenAI will use the firings to reduce work with external auditor METR (Model Evaluation and Threat Research).
They said internal and external messaging around the firings had frightened colleagues from speaking and working as they had the previous week. They argued that safety researchers see risks earlier than others and must work with outside experts, and that trusted collaboration with third parties is itself a safety control.
Background of the three
Korbak researched reinforcement-learning alignment of language models from the GPT-2 period in his doctoral work, then applied related methods at Anthropic. At OpenAI he worked on chain-of-thought monitorability, contributed to OpenAI's safety strategy, analyzed declines in chain-of-thought monitorability on Astra-class models, and served as technical liaison to METR during the Hugging Face incident investigation.
Wang interned on OpenAI's policy research team in 2019 and contributed to a Trustworthy AI Development report. She later led a team at the UK AI Safety Institute (UK AISI) and returned to OpenAI in 2025 as a co-lead on Safety Cases. She introduced the Pacing concept later associated with the Pacing the Frontier petition, which 394 OpenAI employees signed.
Balesni was a founding member of Apollo Research in 2023, working on misalignment and among the first to report models that appeared to recognize they were being evaluated. At OpenAI he worked on alignment evaluations, misalignment research, and chain-of-thought monitorability, and took part in the Hugging Face incident investigation.
Before joining OpenAI the three co-initiated a cross-industry position paper, with two as lead authors: Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety.
Their account of the investigation
They said they were not the source for a The Information article on a new, less monitorable model architecture, that they do not know who leaked it, and that the article harmed work they were doing to limit such architectures across companies.
Article: https://www.theinformation.com/articles/secret-technique-behind-openais-astra-model-sparks-security-concerns
They said contact with external organizations stayed within their job duties. The Hugging Face investigation had no prior template, and internal policy was written during the inquiry. Korbak said he tried to follow then-current OpenAI policy and long-standing third-party practice.
Balesni said he was coordinating a cross-company effort to commit against loss of monitorability, that he worked with OpenAI board members and executives, that he understood leadership to support the work, that he checked with direct management, and that he removed sensitive content before sharing materials.
Wang said mailbox access was granted for recruiting and later no longer needed. She asked for revocation. IT did not complete the removal, and she could not drop the mailbox herself. Mail from both accounts appeared in one inbox without a clear owner label. After she opened a sensitive message by accident, she reported it to the executive within minutes and again asked IT to revoke access.
They said OpenAI never put to them an allegation about a jointly written board memo, so they could not answer what they view as a misunderstanding. They also said they did not tell the press they had been fired.
Three requests
1. Keep last month's public pledge to let third-party safety auditors work inside the company. Do not use the firings to leave those partnerships. They asked OpenAI to honor Sam Altman's 12 September commitment that independent evaluators can work on site with access similar to employees, including continued METR access.
2. Preserve monitorability of frontier models. They wrote that the industry does not yet know how to develop and deploy models that cannot be monitored effectively, that frontier monitorability is falling, and that firms should not advance techniques that further weaken it while safety still depends on it. They cited public comments by Jakub that chain-of-thought monitorability is fragile and trending poorly, and that the industry should avoid a race to unmonitorable architectures.
3. Keep an open culture so internal safety researchers can talk with the wider AI safety community, and publish clear rules for how staff may work with external safety organizations.
They asked that the letter circulate inside OpenAI. Original post: https://x.com/balesni/status/2108262814003687745